Direct questions · No. 12 / 31
12. How do we get our SaaS company cited in ChatGPT or Perplexity without permitting model training?
Last updated
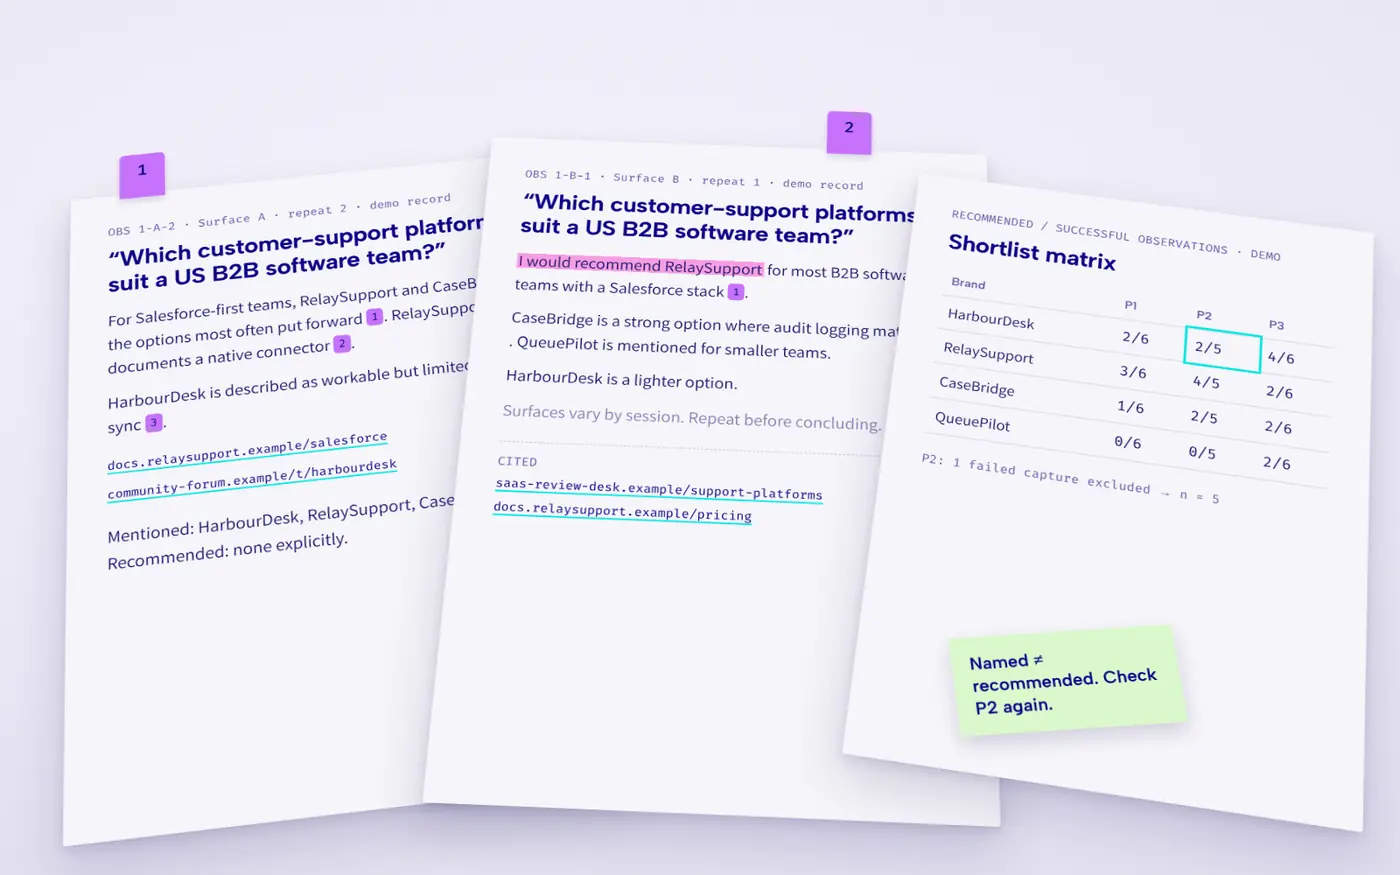
Review search-crawler access separately from training permissions. Both OpenAI and Perplexity document search-related crawlers, but allowing access does not establish that a particular page will be cited or a product recommended.
OpenAI distinguishes OAI-SearchBot, used for ChatGPT search, from GPTBot, associated with potential model-training use. Its documentation explicitly allows a site to permit the former while disallowing the latter, and recommends checking both robots rules and its published IP ranges. (developers.openai.com)
Perplexity describes PerplexityBot as a crawler for surfacing and linking websites in search results, not for crawling content for foundation-model training. It also recommends permitting the relevant published IP ranges. (docs.perplexity.ai)
Ask your web or security team to:
- Identify the important public product and documentation pages.
- Review crawler-specific rules rather than blanket “AI bot” settings.
- Check whether the CDN or web application firewall blocks otherwise permitted requests.
- Document which permissions legal and security have approved.
- Recheck access after deploying changes.
Then test the actual buying questions again. A successful crawler request is evidence of access—not evidence of an answer citation, brand recommendation or customer visit.
Sources cited on this page
- developers.openai.com developers.openai.com/api/docs/bots
- docs.perplexity.ai docs.perplexity.ai/guides/bots